Celebrity Explorer
A static research tool for comparing public figures in aggregate, with sources, confidence levels and honest caveats.
What it is
Celebrity Explorer is a static research and comparison tool for public figures. You can search, filter, chart and compare people by profession, era, birth decade, gender, wealth tier, political leaning and several other structured fields, and see the result as charts, a table or a side-by-side comparison. Its working title in the app is the Celebrity Representation Explorer, and the hosted edition calls itself COCD, the Completely Open Comparable Database. It was built with AI agents on The Late Build, and it is a good example of a data project where the interesting work is not the interface but the care taken with the data.
As of this writing the database holds 1,042 unique active records, of whom the dashboard counts 910 as alive. Everything is open: the data file is a plain JavaScript file with a JSON backup, the code runs in the browser with the Chart.js library bundled locally, and nothing needs a server to work.
How you use it
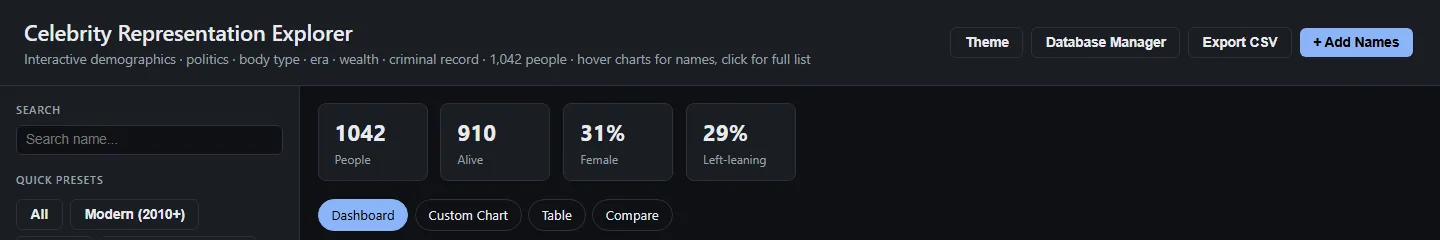
- Start with a preset such as Modern (2010 and later), Classic, Actors and Comedians, Musicians or Alive, or search by name.
- Open the core filters. They cover profession, gender, body type, political leaning, immigrant status, wealth tier, peak era and birth decade, among others. Apply them together and an option to exclude Unknown values keeps charts honest when data is thin.
- Read the dashboard. Pie, doughnut and bar charts show how the filtered group is distributed. Hovering shows names and clicking opens the full list.
- Build your own chart. Pick a dimension and a chart type and a theme, then compare two dimensions side by side in Compare.
- Use the table to browse records and export to CSV.
Editing and adding people
A Database Manager lets users add or edit a person, browse and delete records, and import or export the data file. Edits are kept in the browser’s local storage as a working copy until a new data file is downloaded and shared. A separate Add Names flow generates a structured research prompt that you can give to another assistant or researcher, then you paste the returned JSON back in to import it. New names are skipped when a case-insensitive match already exists, and imported records are marked as user-added and in need of verification.
The data, and how it was handled
This is the part worth reading even if you never open the tool. Every record has a name, years, gender, profession and other fields, plus a provenance field that says whether it came from the original database, was added by a user or was a project record that a user edited, and a verification status that reminds readers when something needs checking. A written caution sits at the top of the project notes: this is a comparison and research aid, not an authoritative source.
- Wealth tiers use a fixed vocabulary from under one million to one trillion and more, plus Unknown. Boundaries belong to the higher tier, so exactly one billion dollars falls in the one-billion tier. Figures are approximate and time-sensitive, and tier migrations are logged in reports.
- Sourcing. An enrichment pass on August 9, 2026 added public-entity and biography sources from open knowledge bases to 184 placeholder records. Enriched records can carry per-field confidence levels, direct source links per field and a short note about how a value was assigned. Low-confidence wealth and body-type values are deliberately labeled as approximations.
- No guessing about people. Political values stay Unknown when the person has no clear public political record; an occupation, an employer or an audience is not treated as proof of personal ideology. Unknown means unknown, not an absence of the characteristic.
- Removing the unverifiable. Records whose claimed identity could not be verified were pulled out of the active comparisons and kept in a separate file.
- Checks. A verification script checks the database structure, the JavaScript syntax, prompt generation and the import workflow. A set of scripts also reconciles candidate additions and validates proposals before they are merged.
Why a tool like this needs caveats
Fields such as race and ethnicity, political leaning, body type or criminal record are contested, change over time and are easy to misuse. The tool does not claim otherwise. Its purpose is to let someone look at representation across professions and eras in aggregate, with sources and confidence visible, and not to label individuals. Treat any single record as a pointer to better sources, and treat any aggregate as a rough picture whose accuracy depends on the underlying fields. That is the same stance the project takes toward AI output in general, and it is the reason the verification fields exist.
The hosted edition and privacy
The hosted version wraps the explorer in a small full-stack site with pages for adding names, for owner review of submissions, and for a privacy statement. The privacy page is specific: no analytics, advertising trackers, tracking pixels, device fingerprinting or cross-site cookies; browsing the database does not create a visitor profile; information is stored only when someone deliberately submits a correction, a removal request, a new record or feedback; and public visitors are no longer asked for an email address. A removal request path exists because a database about real people should have one.
How it was built
The original app was a single HTML file with the data embedded, and a loading problem when opened from a local file led to a rebuild: the interface stays in one file and the database moved to a neighboring script file that loads without the restriction that broke the first version. The project then grew a collection of Node scripts for research and merging, each doing one job (importing candidates, applying enrichment, auditing categories, validating proposals). The agent workflow behind it matches the one described on The vibe-coding workflow: small scripts with clear inputs, reports saved next to each pass and a rule that research results are proposals until validated.
Extending the schema
Adding a new comparison dimension means adding a field to the data and a filter definition; the app preserves unknown extra properties when records are loaded, edited, imported or exported, so a richer record is never trimmed by an older workflow.
Limitations
- The database is a sample of 1,042 public figures, not a census, and its mix reflects how names were collected.
- Several fields are coarse approximations, and some are unknown for many people.
- Time-sensitive facts such as current office or wealth need re-checking against current sources.
Compare it with the other web tool on this site, the two Game of Life apps, or return to the projects index. To see how much checking an AI-assisted data project needs, watch a data session on the livestream.